I spent three months watching my sales team fight the same losing battle.
They’d pull a list from the CRM and start reaching out. Then boom, half the emails bounced. The phone numbers? Disconnected or plain wrong. Company names sat in five different formats. Sound familiar?
So I finally dug into data enrichment vs data cleansing properly. And honestly? I’d treated them as the same thing for years. They’re not. After rebuilding our whole pipeline, I found the mistake most teams make: they enrich dirty data. That’s painting a crumbling wall.
Let me save you the eight weeks it took me to sort this out. 👇
📌 TL;DR: Data cleansing FIXES your existing data so it's accurate, consistent, and de-duplicated. Data enrichment ADDS new attributes from outside sources to make that data more valuable. Cleanse first, enrich second. Enriching messy records just multiplies the mess and the cost.
Data Enrichment vs Data Cleansing: What’s the Difference?
Data cleansing corrects and standardizes the records you already have, while data enrichment adds new attributes from external sources. Cleansing makes your data TRUE. Enrichment makes it DEEPER.
Here’s the model I use with every team:
Cleansing → “fix what’s broken.” Enrichment → “add what’s missing.” You cleanse to earn trust in a record. You enrich to make the trusted record worth more.
And the order is everything. Clean first, and every dollar of enrichment goes further. Skip cleansing, and you’re paying to append fresh attributes onto duplicates and typos. I’ve done both. One of them hurt.

Cleansing vs Enrichment, Side by Side
When someone on my team mixes these up, I just pull up this table:
| Dimension | Data Cleansing | Data Enrichment |
|---|---|---|
| Goal | Accuracy and consistency | Depth and context |
| Works on | Data you already have | Adds data from outside |
| Fixes | Duplicates, typos, bad formats | Missing attributes |
| Typical steps | Validate, dedupe, standardize | Append firmographics, domains |
| When | First | After cleansing |
| Answers | Is this record correct? | Does this record know enough? |
They’re not rivals. They’re a relay. Cleansing hands a clean baton to enrichment. And underneath both sits data integrity, the discipline that keeps records correct as they move between systems.
What Is Data Cleansing?
Data cleansing removes errors and inconsistencies from your existing records so your team can trust what they see. Think of it as quality control for your database: validation, standardization, deduplication, and error correction.
When I audited our CRM, I found duplicate contacts, misspelled company names, dead email addresses, and phone numbers in six formats. Messy doesn’t cover it. So cleansing went to work on the specifics:
- Data deduplication so the same account stops showing up three times
- Standardizing formats so “United States,” “USA,” and “US” become one value
- Validating emails against DNS and MX records before you ever send
- Correcting typos and parsing errors that make records unusable
- Filling gaps with survivorship rules (keep the best value across duplicates) instead of guesses
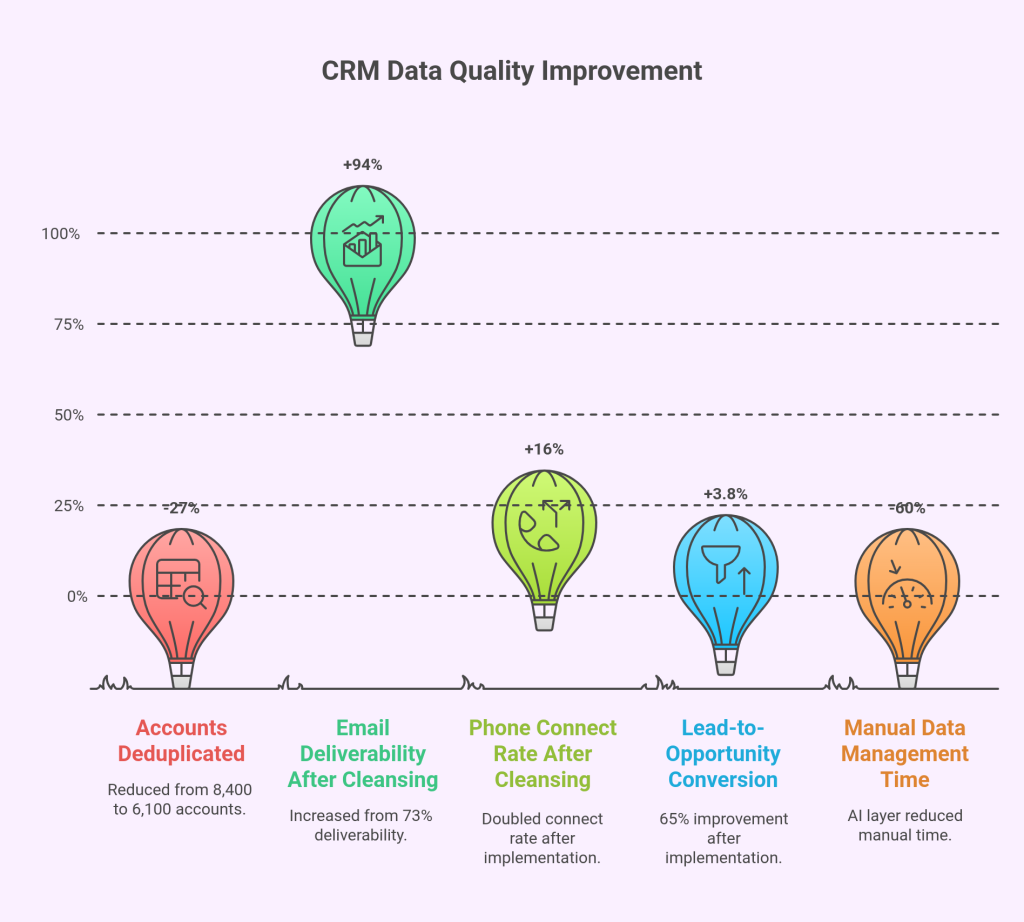
Our first cleansing pass pushed data quality scores from 62% to 89% in three weeks. And that’s not a vanity number. Bad data is expensive. IBM’s overview of data cleansing is a good primer, and the well-known Harvard Business Review estimate from 2016 put bad data at roughly $3 trillion a year in the US alone.

Here’s what cleansing did for us in the real world. Before it, reps burned 40% of their time chasing bad leads. Email deliverability sat at 73%. After:
- Email deliverability climbed to 94%
- Phone connect rates doubled, from 8% to 16%
- Sales cycles shortened by 11 days
- The team saved about 12 hours a week on manual research
Cleansing also protects you legally. Rules like the GDPR and the CCPA expect the personal data you hold to be accurate. Clean data isn’t a nice-to-have there. It’s the law.
What Is Data Enrichment?
Data enrichment adds external attributes to records you already own. You start with a name and an email. You end with company size, industry, revenue, tech stack, and a verified domain. Same contact, far more context.
The first time enrichment ran on our freshly cleaned list, it felt like flipping on the lights. Lead scoring finally made sense. Reps stopped chasing tiny accounts that only looked big. And here’s the surprise that stuck with me: clean data made enrichment roughly 3x more effective. The two compound.

Common enrichment moves include:
- Appending firmographics: employee count, revenue band, industry
- Adding a verified company domain to a bare company name
- Layering in technographics (the tools a company runs) and buying signals
- Filling in job titles, seniority, and location
The catch? Enrichment can’t fix broken data. If a record is a duplicate or the name is garbled, enrichment happily attaches accurate new fields to the wrong row. That’s why matching matters so much. Good data matching is what lets enrichment land on the right record every time.
Where Data Cleansing Wins
Cleansing wins whenever your existing records contain errors you can see. Bounced emails. Duplicate accounts fighting over one rep. Reports nobody believes. Those are cleansing problems, and no amount of new attributes fixes them.
It also wins on risk. Wrong personal data is a compliance problem, not just an annoyance. And it wins on cost, because every downstream tool bills you for the junk rows too.
Think of dirty data as a leak. You plug the leak before you pour anything new in.
Where Data Enrichment Wins
Enrichment wins when your records are accurate but thin. The email works. The company name is spelled right. But you can’t score the lead, size the account, or route it, because the context isn’t there.
That’s where enrichment earns its budget: lead scoring, territory planning, segmentation, personalization. A bare name-and-email row can’t do any of those jobs. An enriched one can.
But watch the order math. Enrich a duplicate and you’ve paid twice to learn the same facts about one account. On our 50,000 records, that waste would have been very real money.
Where They’re the Same
Both are data quality work on records you already own, and both exist for one reason: better decisions, cheaper. Neither creates leads. They make the leads you have usable.
The overlaps run deeper than most write-ups admit:
- Both fail on garbage inputs. Cleansing can’t rescue a fake entry, and enrichment can’t match it.
- Both are ongoing. B2B data decays as people change jobs, so one pass of either goes stale.
- Both depend on matching, whether that’s fuzzy matching duplicates or matching a row to an external source.
- Both need a quality check after they run. Trust, then verify.
Different axis, same goal. Cleansing works on truth. Enrichment works on depth. Your CRM needs both to be worth opening.
How Both Improved Our CRM by 67%
Here’s the sequence that took our CRM quality up 67% over eight weeks. It’s boring on purpose. Boring works.
- Audit and profile the data.
- Cleanse: dedupe, standardize, validate.
- Enrich the clean records with firmographics and verified domains.
- Set up ongoing checks so it stays clean.
The data quality flywheel only spins if that last step exists.
And here’s the part nobody tells you: the loop feeds itself. The verified domains we appended in step 3 exposed bad rows we’d missed in step 2. Enrichment output became cleansing input. That’s when the whole thing clicked for me.
💡 The math that convinced my CFO: 50,000 records → cleanse (quality 62% → 89%) → enrich clean records → deliverability 73% → 94% + connect rates doubled. Enriching BEFORE cleansing would have wasted budget on duplicates. Order is the whole game.
Which Should You Prioritize?
Cleansing first, almost always, because enrichment multiplies whatever it touches. Clean records get more valuable. Dirty records get more expensive.
So run a two-question test. Do my records contain errors, duplicates, or bad formats? Cleanse. Are my records accurate but thin on context? Enrich. Most teams need both, in that order, on repeat. Strong data preparation ties the whole loop together.
One practical starting point: the fastest enrichment win I know is turning messy company names into verified domains, since so much else keys off the domain. That’s the exact job a tool like Company URL Finder handles once your list is clean.
How I Tested This
Every number above comes from one place: rebuilding my own team’s CRM across eight weeks, roughly 50,000 records. Not a lab benchmark. So treat my 62%-to-89% and 3x figures as one team’s honest results, not industry averages.
Your decay rates and match rates will differ. Spot-check ten records by hand after any cleansing or enrichment pass. Ten manual checks tell you more about your data than any article, including this one.
Cleansing settled? Enrichment has more lookalikes. I’ve compared it with data augmentation too, plus data enhancement, data hydration, and data integration, if you’re untangling the whole family.
Related Articles
- Data Enrichment vs Data Integration
- Data Enrichment vs Data Hydration
- Data Enrichment vs. Data Cleansing
- Data Enrichment vs Data Augmentation
- Data Enrichment vs Data Enhancement
🚀 Try Our Company Name to Domain Service
Discover the fastest and most accurate tool to convert company names to domains. It takes less than a minute to sign up, and you can start seeing results right away.
Start Free Trial →Frequently Asked Questions
What is the difference between data enrichment and data cleansing?
Data cleansing fixes existing data by removing duplicates, correcting errors, and standardizing formats. Data enrichment adds new external attributes like company size, industry, or a verified domain. Cleansing makes records accurate; enrichment makes them more useful. You cleanse first, then enrich.
Should I cleanse or enrich my data first?
Cleanse first, in almost every case. Enriching dirty data attaches new attributes to duplicates and errors, which wastes budget and spreads the mess. Clean the records so they’re accurate and unique, then enrich them. In my testing, clean data made enrichment about 3x more effective.
What is the difference between data cleaning and data cleansing?
Nothing meaningful. “Data cleaning” and “data cleansing” name the same process: finding and fixing errors, duplicates, and inconsistencies in a dataset. Some teams save “cleansing” for the formal, rule-based enterprise version, but the goal is identical. Data scrubbing is a third name for it.
What does data enrichment mean?
Data enrichment means improving records you already own by adding trustworthy new attributes from internal or external sources. For a B2B contact, that often means appending firmographics, technographics, verified emails, and the company domain, so the record supports better targeting and scoring.
What’s the opposite of data enrichment?
There’s no exact opposite, but data minimization is the closest idea. It’s the practice of collecting and keeping only the data you truly need. Enrichment deliberately adds attributes; minimization deliberately limits them, usually for privacy and compliance.
How often should I cleanse and enrich my data?
Treat both as ongoing, not one-time projects. Data decays fast, since people change jobs and companies rebrand. I run automated cleansing continuously and re-enrich key records on a schedule, quarterly for most fields and more often for volatile ones like job titles.
Is data cleansing part of ETL?
Yes, usually. In an ETL pipeline (extract, transform, load), cleansing happens in the transform stage, where data gets validated, standardized, and de-duplicated before loading. But cleansing isn’t only an ETL step. CRMs and marketing databases need the same fixes on a regular schedule.
Now go check ten records in your CRM. If they make you wince, you know exactly where to start. You got this.