

I once burned $28,000 on secondary data before I understood how to use it. True story.
Here’s how it went. I bought contact databases from three providers. Then I enriched roughly 150,000 leads in a single week. It felt like progress.
It wasn’t. Because 41% of those emails bounced.
The data was stale. Our reps chased people who had changed jobs months earlier. And I got to explain that ROI to my boss in Hamburg with a straight face. That one stung.
So let me save you the tuition I already paid. Secondary data isn’t the problem. Secondary data you never validate? THAT’s the problem.
📌 TL;DR: Secondary data is information someone else collected for their own reasons that you reuse for yours. It's not primary data (you gathered it) and it's not the same thing as third-party data (aggregated and resold to anyone). The wins: cheap, fast, broad, historical. The catches: relevance gaps, quality you can't control, compliance risk. The rule → validate before you trust, standardize before you merge, refresh before it rots.
What is secondary data?
Secondary data is information someone else collected, for a different purpose, that you reuse in your own analysis. That’s the whole definition.
Think about it like this. You need company revenue figures for lead scoring.
You could call every company and ask. That takes years and a budget nobody signs off on. Or you buy a dataset from a provider who already did that legwork. Same insight. Fraction of the cost.
That second path is secondary data.
I learned the distinction the hard way. Once, I tried to build technographic data myself, meaning a record of which software each company runs. Surveying companies about their tech stacks got me a 3% response rate and ate six months. Existing sources gave me 85% coverage in 48 hours.
So yes, reused data makes analysis possible that fresh research simply can’t touch at that speed. It’s a core input for any serious data enrichment program.
According to the standard definition of secondary data, the defining trait isn’t where it lives. It’s that someone gathered it for a purpose other than yours. Keep that in mind. It explains almost every advantage AND every headache below.

What is the difference between primary and secondary data?
Primary data you collect yourself. Secondary data someone else collected and made available. Third-party data is aggregated from many sources and sold to anyone.
Who did the collecting, and who else can buy it. That’s the whole game.
Here’s the side by side I wish someone had handed me on day one:
| Data type | Who collected it | Exclusive to you? | Cost & speed | Best for |
|---|---|---|---|---|
| Primary | You, directly | Yes | High cost, slow | Questions only you can answer |
| Secondary | Another organization | Sometimes | Low cost, fast | Broad market and firmographic coverage |
| Third-party | Aggregators, from many sources | No | Lowest cost, instant | Scale outreach, with compliance care |
What is primary data?
Primary data is information your team collected directly, for your exact question.
Customer surveys. Website behaviour. Support tickets. Purchase records. I’ve built all of them, and the upside is real: perfect relevance, full quality control, nobody else owns it.
The downside is just as real. I once spent three months and $47,000 on market research that a $3,200 dataset covered anyway. So now I save fresh research for the questions no vendor can answer.
What is secondary data in practice?
In practice it’s whatever an outside organization already gathered and now shares or sells.
Firmographic providers, meaning vendors who sell company attributes like size and industry. Technographic platforms. Intent networks. Contact databases. Public records.
You get instant coverage that would be impossible to build alone. But it wasn’t gathered for you, so relevance varies and quality depends on the provider’s method. Which is exactly why I never trust an accuracy claim without testing it.
What is third-party data?
Third-party data is secondary data aggregated from many sources and sold to whoever pays.
It scales beautifully. And it’s cheap. But two things bit me hard.
First, quality: duplicates, conflicts, murky provenance. Second, compliance. Aggregated collection often lacks a clear consent chain, and under GDPR that’s a genuine liability.
This is where data governance stops being a slogan and starts being insurance. I mapped the full ownership tiers in our guide to first, second, and third-party data.
🔍 Quick gut check: If you can't answer "who collected this, and did they have consent?" about a dataset, treat it as a compliance risk until proven otherwise. Vet the provenance BEFORE it touches your CRM, not after legal asks.
What are examples of secondary data?
Secondary data splits into two buckets: external and internal. External was collected outside your walls. Internal was collected inside them, for a different job.
Both are gold if you know where to look.
External secondary data
External sources give you information gathered by specialist providers and public bodies. I’ve gone deeper on external data and how to fold it into your systems.
Here’s what I actually pull from, day to day:
- Firmographic data: company size, revenue, industry, corporate hierarchy. This is what powers account scoring and territory design.
- Technographic data: the software a company runs. When I enriched target accounts with it, the ones using complementary platforms converted at 3.2x our baseline.
- Intent data: research signals collected across publisher networks. Adding it lifted our pipeline velocity 38%.
- Contact data: verified emails, phones, titles. Match rates swing hard by geography, and mine ran far higher in the US than in the EU.
- Public records: government databases, regulatory filings, trade-association research, census data. Authoritative, and often free.
Internal secondary data
Internal secondary data is information your own company collected for a different reason than the one you have now.
This is the free money most teams walk straight past:
- Support tickets: gathered for service, packed with churn signals and feature requests.
- Sales call notes and recordings: objection patterns and competitive gaps, already sitting there.
- Product usage logs: originally for monitoring, perfect for health scores and segmentation.
- HR and finance systems: hiring velocity and procurement records that hint at growth.
And here’s the multiplier. Clean company identity lets you join the two buckets reliably. Get the company key wrong and your internal records attach to the wrong external row.
Where do you find secondary data?
You find it in four places: statistical offices, research repositories, commercial providers, and your own systems.
Let me take them in order of cost.
- National statistics offices. The U.S. Census Bureau and the UK Office for National Statistics publish industry, size, and economic data at zero licensing cost. Underrated. Genuinely.
- Open research repositories. Places like World Bank Open Data host cleaned, documented datasets with real methodology notes attached.
- Commercial providers. Firmographic, technographic, intent, and contact vendors. This is where the money goes, and where sourcing data from vendors becomes a skill of its own.
- Your own stack. Free, already licensed, already yours. Start here before you buy anything.
My honest advice? Exhaust the free tiers before you sign a contract. I’ve watched teams pay for census figures twice.
Is secondary data qualitative or quantitative?
It can be either. The label describes where the data came from, not what shape it takes.
Census figures, firmographic counts, and financial filings are quantitative. Published case studies, review-site content, and industry commentary are qualitative. In B2B work you usually blend both, and our breakdown of qualitative and quantitative data covers when each one earns its place.
How do you analyze secondary data?
Carefully, and in a fixed order. Because you didn’t control the collection, your job shifts from gathering to VERIFYING.
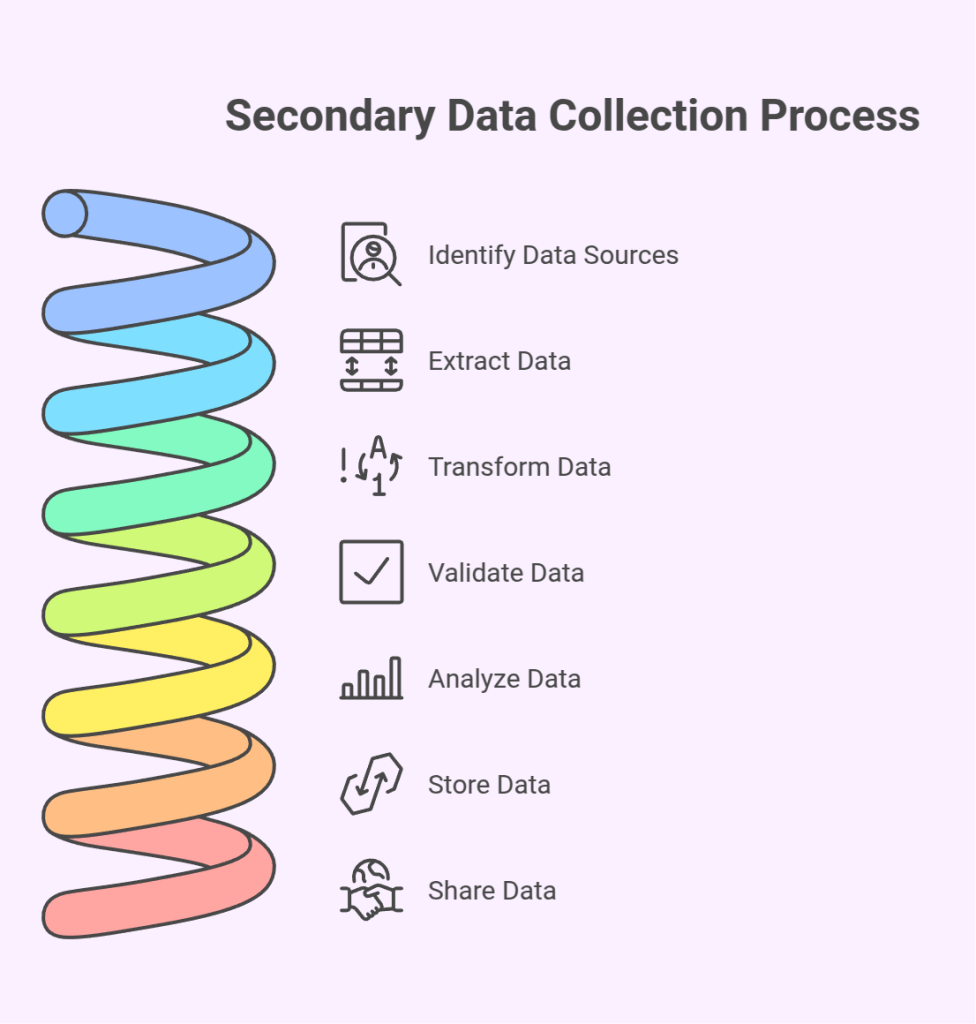
Here’s the four-step routine I run every single time.
1. Evaluate source quality
Score every source before you touch it. Provider reputation, method transparency, sample size, refresh frequency, geographic coverage.
I weight the strong sources heavier and triangulate across several, meaning I check the same fact in three places. When two good sources disagree, that gap is telling you where to dig.
2. Clean and standardize
Secondary data arrives in a dozen formats. So I standardize company names, map industry codes to one taxonomy, convert currencies, and resolve duplicates through data matching.
Mapping every vendor’s industry labels onto the NAICS system, a shared US industry classification, removed most of my cross-source headaches on its own.
3. Validate against data you trust
Cross-check the numbers against records you control. When I did this, revenue figures for private companies varied widely between providers, and employee counts drifted too.
So I built a confidence score from those checks and adjusted for each vendor’s known bias. Validation turns questionable inputs into calibrated ones. That’s the whole point.
4. Analyze within context
Never treat reused data as absolute truth. Note the coverage gaps, the age of the file, and the assumptions baked in.
Then document them, so stakeholders decide with their eyes open. Teams with mature data quality habits run circles around teams that just trust the vendor. Transparent caveats beat false precision every time.
What are the advantages of secondary data?
It does things fresh research flat-out can’t. Here are the wins I keep coming back to:
- Cost. I once covered 200,000 accounts for $3,200. The equivalent survey work was quoted at $180,000.
- Speed. 48 hours versus six months. We launched while competitors were still writing survey questions.
- Breadth. Global coverage, no field team required.
- History. Years of past figures you can’t recreate after the fact. Great for trend work.
- Triangulation. Combining five providers exposed blind spots that any single one hid.
What are the disadvantages of secondary data?
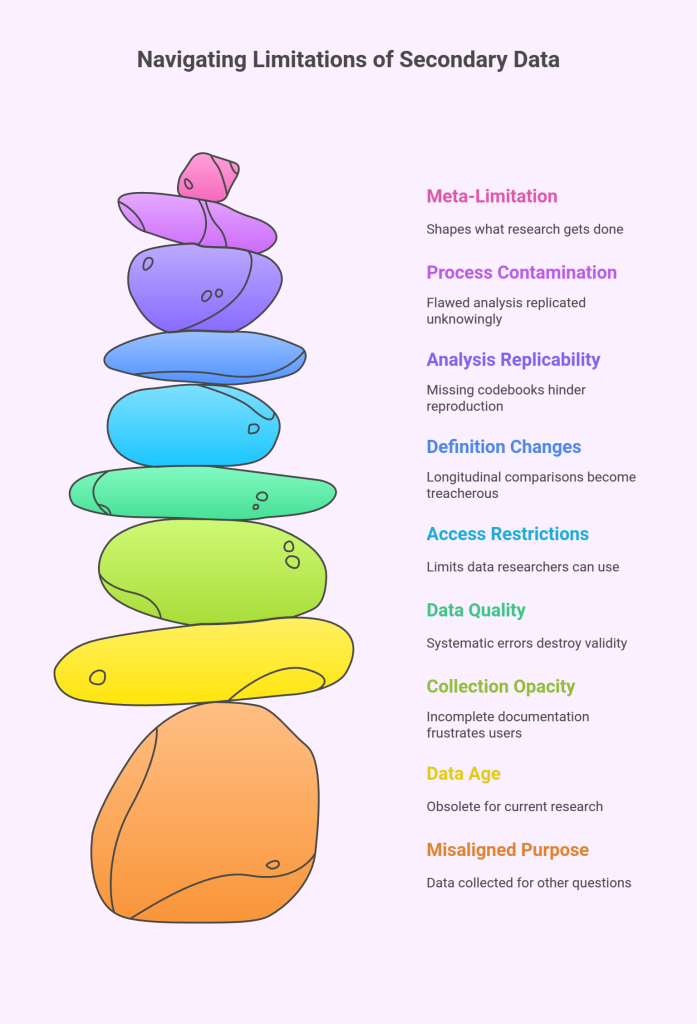
Now the honest part. It comes with real limits, and I learned most of them by getting burned.
Relevance gaps
Someone collected it for their question, not yours. I bought demographic files whose geographic segments didn’t match our territories at all.
And “decision maker” meant something different at every provider. So concept mapping isn’t optional. It’s step zero.
Quality you can’t control
Accuracy varied widely across providers who all claimed the same standard. Contact records decay constantly, no matter how clean the file starts.
Test, don’t trust. Every time.
Cost accumulation
Subscriptions stack up fast. I hit $28,000 a year across firmographic, technographic, intent, and contact feeds before I put usage controls in.
Monitor consumption, or it monitors your budget.
Compliance risk
Several providers couldn’t show a clean consent chain for EU contacts. Under GDPR, that’s a fineable problem rather than a shrug.
So legal review comes before procurement now. Every contract, no exceptions.
The two failures nobody warns you about
Most guides stop at the pros and cons list. But two failures cost me more than everything above combined, and I’ve never seen either one explained properly.
The freshness clock
A dataset isn’t a fixed object. It’s a snapshot with an expiry date you can’t see.
Academic sources treat a file as permanent, and for a census that’s fair. Commercial B2B data behaves nothing like that. People change jobs, companies rebrand, offices close.
The file you validated in January is a different quality asset in July. So I now record a “collected on” date next to every field, not just every file. When a field has no date, I treat it as unverified.
Definition drift
Two providers ship a column with the same name and a different meaning. That’s definition drift, and it silently invents numbers.
One vendor counts contractors in “employee count”. Another doesn’t. One reports group revenue, another reports the local entity. Merge them and your average is fiction.
My fix is boring and it works. Before merging, I pull ten rows from each source and read the field documentation side by side. Ten minutes. It has saved me entire quarters.
💡 Lesson I paid for: Secondary data is an asset until you stop validating it. The moment it goes stale or non-compliant, it flips to a liability sitting inside your CRM. Refresh, re-verify, and re-check consent on a schedule, not "someday".
What I’d do differently
If I could rerun that $28,000 year, I’d change the ORDER, not the budget.
Here’s what I do now. I take a 500-row sample from every provider before signing anything. Then I email-verify it, call twenty numbers, and check ten companies by hand against their own websites.
That whole test takes about two days. It costs nothing beyond my time.
Back in Hamburg I skipped it, because three vendors all showed me accuracy claims in a slide deck and I believed the deck. That 41% bounce rate was the invoice for my trust. The sample test would have caught it in an afternoon.
So run the sample. Always run the sample.
How I know this
The numbers in this article come from my own vendor runs between 2021 and 2026, not from a published survey.
They’re real, and they’re also limited. They cover B2B software and services in Europe and North America, at list sizes between 5,000 and 200,000 records. A different industry or region would give you different match rates.
Provider accuracy also moves. A vendor that tested badly for me two years ago may be excellent today, and the reverse happens too. So treat every number here as a reason to run your own test, not as a benchmark to quote.
Frequently Asked Questions
What is secondary data and examples?
Secondary data is information another organization collected for its own purpose that you reuse for a different analysis. Common examples include census and government data, industry research reports, firmographic databases, technographic platforms, intent networks, and contact enrichment files. The shared trait is simple. You didn’t collect it.
What is the difference between primary and secondary data?
Primary data you collect directly for your own question, while secondary data was collected by someone else for a different one. Primary gives you perfect relevance and exclusive ownership, but costs more time and money. Secondary is faster, cheaper, and broader. You just have to validate it, because you didn’t control how it was gathered.
What are 10 examples of secondary sources?
Census data, industry research reports, firmographic databases, technographic platforms, intent networks, contact enrichment services, regulatory filings, academic journals, news archives, and analyst market studies. Each serves a different purpose. None of them was collected by you originally, which is what puts them all in the same category.
How do you find secondary data?
Start with free public sources, then open research repositories, then commercial providers, and check your own systems throughout. National statistics offices publish industry and economic data at no cost. Open repositories add documented datasets with methodology notes. Buy from vendors only for the fields those two can’t give you.
What is an example of secondary data in real life?
A sales team scoring leads on company size it bought from a data provider is using secondary data every day. The provider gathered those employee counts for its own catalogue. The sales team reuses them for a scoring model nobody at the provider ever imagined. Same file, different purpose.
What are the disadvantages of secondary data?
The main ones are relevance gaps, quality you can’t control, accumulating cost, and compliance risk. Definitions and segments may not match yours, since the data answered a different question. Accuracy varies by provider, contact records decay steadily, subscription fees stack up, and consent chains for regulated regions can be missing.
Is secondary data qualitative or quantitative?
It can be either, because the label describes the source rather than the shape. Census figures, firmographic counts, and financial filings are quantitative. Case studies, review content, and industry commentary are qualitative. Most B2B teams blend both: numbers for scoring, text for context.
How do you keep secondary data accurate over time?
Refresh it on a schedule, re-validate against records you control, and re-check consent for regulated regions. Contact records decay continuously, so quarterly or rolling refreshes are common. Anchor every record to a verified company identity first, so updates land on the right business, then reconcile conflicts between providers.
That’s the whole playbook. Validate before you trust, standardize before you merge, refresh before it rots.
You don’t need my $28,000 lesson. You just need the 500-row sample. Go run it.
🚀 Try Our Company Name to Domain Service
Discover the fastest and most accurate tool to convert company names to domains. It takes less than a minute to sign up, and you can start seeing results right away.
Start Free Trial →


