


I spent three years watching organizations drown in their own data. Spreadsheets multiplied like rabbits. Databases contradicted each other. Teams made decisions on numbers that didn’t match. Honestly? The chaos was expensive, and completely preventable.
Here’s what nobody tells you about modern business. Your data strategy matters more than your data volume. You can have oceans of information and still fly blind.
But here’s the good news 👇🏼
Good data management turns that liability into your biggest advantage. Organizations that treat data as a managed asset consistently out-decide the ones that don’t. So let me break down how it actually works.
30-Second Summary
📌 TL;DR: Data management is the end-to-end practice of planning, collecting, storing, organizing, securing, governing, and using data across its lifecycle. It covers quality, metadata, lineage, privacy, integration, and archival. Do it well and your data works for you. Skip it and it works against you.
What you’ll learn:
- What data management is, and how it differs from governance
- Why it decides whether your analytics and AI projects survive
- The six pillars, from storage to master data management
- Real examples, best practices, and the mistakes I see most
What Is Data Management?
Data management is the end-to-end practice of collecting, storing, organizing, protecting, governing, and using data across its lifecycle. That’s the textbook version. In plain terms, it’s everything you do to make data trustworthy and usable.
Think of it like this 👇🏼
Your business generates a flood of information every day. Customer interactions. Transactions. Operational metrics. Support tickets. Without proper handling, that flood becomes noise instead of insight. The goal is simple. Maximize the value, minimize the risk.
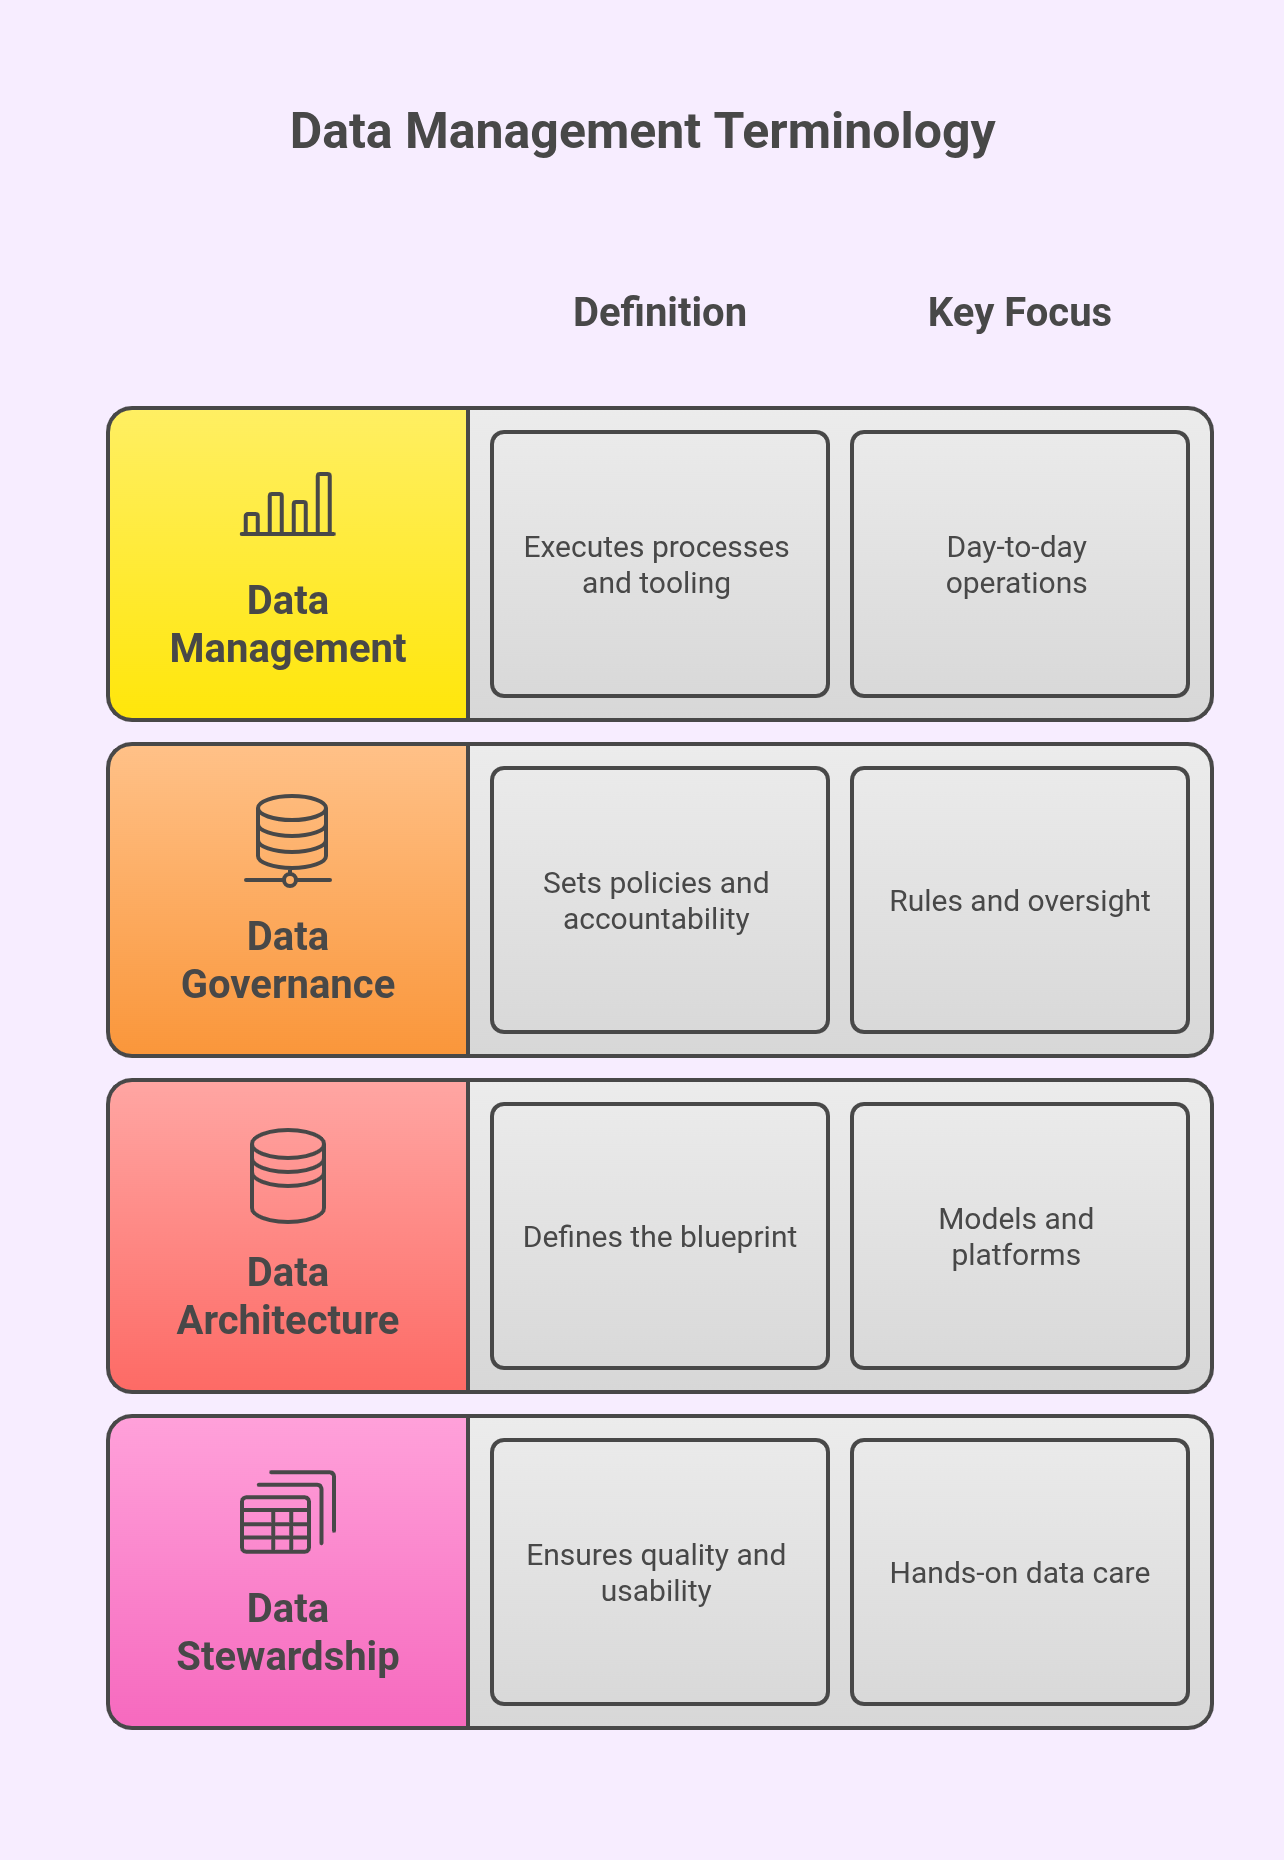
People confuse a few terms here constantly. So let me clear them up:
| Term | What it does | Focus |
|---|---|---|
| Data Management | Executes the processes and tooling | Day-to-day operations |
| Data Governance | Sets policies and accountability | Rules and oversight |
| Data Architecture | Defines the blueprint | Models and platforms |
| Data Stewardship | Keeps data usable and clean | Hands-on data care |
I learned this distinction the hard way, my friend. At one client, I treated data governance and management as the same thing. The project failed in six months because nobody understood their actual job. These aren’t interchangeable. Confusing them creates chaos.
And in the world of B2B data and lead generation, this foundation is everything. Clean, well-managed records are what make data enrichment and accurate targeting possible at all. If you want the neutral framing, the standard definition of data management covers the same ground, from creation right through to deletion.
Why Data Management Matters
Every successful digital initiative I’ve seen started with solid data management. Every failure started without it. That’s the what. Here’s why it pays 👇🏼
It Turns Data Into a Trusted Asset
Good management gives every team one set of numbers they can actually believe. Sounds obvious. It almost never happens by default.
Here’s what happens instead in most companies. Teams distrust the reports. Analysts spend their week cleaning instead of analyzing. Executives fall back on gut feel, because the figures contradict each other.
I’ve sat in meetings where three departments presented three different revenue figures. Same quarter. Same company. Different answers. Strong data quality, tracked across accuracy, completeness, timeliness, validity, consistency, and uniqueness, is what closes that gap. At one B2B firm I worked with, weekly reconciliation meetings went from 12 hours to zero.
It Sets the Foundation for Digital Transformation
Digital transformation fails without data management. Period. I’ve consulted on projects where the winners fixed the foundation first, and the losers rushed straight into analytics and AI.
Why does that keep happening? Cloud migrations expose the mess you already had. Legacy systems carry decades of inconsistencies. Move that without fixing it, and you just move the chaos faster. According to IDC’s data creation research, global data volume keeps climbing into the hundreds of zettabytes, most of it unstructured. Handling that takes real discipline.
It Keeps You Governed, Compliant, and Secure
Regulations keep multiplying, and each one demands specific practices from your data organization. The General Data Protection Regulation in Europe. The California Consumer Privacy Act. HIPAA. PCI DSS. The EU AI Act. Missing them gets expensive fast.
According to IBM’s Cost of a Data Breach Report, breaches tied to poor handling run into millions per incident. The GDPR text also grants rights like erasure and portability. You can’t honor either one without knowing where personally identifiable information lives. Compliance isn’t optional anymore. It’s survival.
Here’s the cheat sheet that’s saved multiple clients 👇🏼
| Regulation | Key requirement | Management action |
|---|---|---|
| GDPR/CCPA | Data minimization | Retention policies |
| HIPAA | PHI protection | Access controls |
| PCI DSS | Payment security | Tokenization |
| EU AI Act | Explainability | Lineage tracking |
It’s What Makes Generative AI Work
Generative AI only works when the data feeding it is clean and well managed. Without that, your models produce garbage. And they do it confidently.
I tested this myself. Same model. One version fed properly managed data, one fed typical enterprise chaos. The quality gap was staggering. Feature stores, vector databases, and retrieval setups for large language models all live or die on the management underneath them.
💡 Remember: Your AI strategy is only as good as your data management strategy. Fix the foundation before you chase the model.
The Key Pillars of Data Management
Let me walk you through the six pillars I’ve seen change organizations. Each one needs its own attention 👇🏼
Storage: Warehouse, Lake, or Lakehouse
Your storage choice shapes everything downstream. A lakehouse, for the record, is a platform that puts warehouse-style tables on top of cheap lake storage. Here’s my quick decision frame:
| Architecture | Best for | Key strength |
|---|---|---|
| Data warehouse | Governed BI, standard metrics | Structured analytics |
| Data lake | Raw, large-scale, multi-format | Flexibility |
| Lakehouse | ACID tables plus BI and AI together | Unified platform |
The lakehouse is my default recommendation now. It blends warehouse reliability with data lake flexibility. But I’ll be honest with you. I wasted two years pushing warehouse-only strategies before I saw it. Match the architecture to your team skills, latency needs, and budget.
Data Fabric and Hybrid Cloud
A data fabric is a metadata-driven layer that connects data across every environment you run. On-premise legacy. Public cloud. Private cloud. Edge. Queries route automatically, and governance applies consistently.
I tested fabric setups at three enterprise clients. Access patterns improved and query performance climbed. Governance finally became consistent across systems that had been siloed for years. But a fabric needs metadata maturity first. Don’t attempt it without solid cataloging in place.
Integration and Processing
Integration connects your scattered databases into flows people can actually use. Without it, silos persist. The patterns I lean on:
- Batch processing: classic ETL for large, scheduled updates.
- Stream processing: real-time change capture, for when freshness matters.
- Data contracts: written agreements between producers and consumers that stop breaking changes.
I can’t overstate how much data contracts improved my success rate. Before them, schema drift broke my pipelines constantly. So pick orchestration tools based on latency and complexity, not on hype.
Governance and Metadata
Governance sets the rules. Metadata, meaning the data that describes your data, supplies the context. Together they make analytics trustworthy.
Honestly, governance scared me at first. It sounded like bureaucracy that slows everything down. I was wrong. Good governance speeds decisions up, because teams move faster when they trust what they’re reading. The professional body behind the DAMA data management body of knowledge treats these as separate knowledge areas for exactly that reason. Here’s the split I implement:
| Role | Responsibility |
|---|---|
| CDO | Policy and strategy |
| Data owner | Accountability for outcomes |
| Steward | Quality and usability |
| Engineer | Technical controls |
| Privacy officer | Legal compliance |
Security and Observability
Security protects the asset, and observability tells you the moment it breaks. Start by classifying data into public, internal, confidential, and restricted. Anything holding personally identifiable information belongs in the top two tiers.
Then layer on RBAC, which grants access by job role, and ABAC, which grants it by context like location or purpose. Add encryption at rest and in transit. Mask sensitive fields in analytics environments. Different classes, different controls.
Observability answers one question. Is your data healthy right now? I track freshness, volume, schema, distribution, and lineage, the record of where every field came from. Catching a break before it reaches a dashboard beats explaining it afterward.
Master Data Management
Master data management, or MDM, creates one golden record for each core entity: customers, products, vendors, employees. Without it, the same customer shows up three different ways in three systems.
I ran an MDM project at a retail client with 4.2 million “customers” in its databases. After deduplication? 2.1 million actual people. Clean entities make everything downstream better. Just don’t try to boil the ocean. Start with your most critical entity, perfect it, then expand.
Examples of Data Management in Practice
The clearest example of data management is one customer record that stays consistent across CRM, billing, and support. That’s the actual work, not the theory. Here’s what it looks like day to day 👇🏼
- Golden records: merging duplicate accounts so sales, finance, and support all see the same customer.
- Automated quality tests: checks that flag a row-count drop or a null spike before a dashboard breaks.
- Migrations that hold up: moving a legacy database to the cloud with integrity and history intact.
- Deletion workflows: a GDPR erasure request that propagates everywhere personal data lives, backups included.
- Retention rules: archiving old records on a schedule instead of hoarding everything forever.
Notice what’s missing from that list. No vendor names. Each one needs an owner, a shared definition, and a schedule, and that’s the boring truth most tool demos skip right past.
Data Management Best Practices
Name an owner for every dataset that matters, before you buy a single tool. An effective data management strategy starts with accountability, not software. Here’s the order I use with clients:
- Agree on shared definitions first, so “customer” means one thing everywhere.
- Add freshness tests to the pipelines your people actually watch.
- Publish one data contract and prove it works before you write ten.
- Classify your data, then protect it by class instead of guarding everything equally.
- Review quality on a schedule, never only after an incident.
- Begin master data management with a single entity, usually the customer.
Boring? Maybe. But this sequence survives reorgs, budget cuts, and turnover. Big-bang programs rarely do.
📌 Start here this week: Assign owners for your top 20 datasets → add freshness tests to critical pipelines → publish one data contract → mask every confidential field → track five core KPIs monthly.
Common Data Management Mistakes
The most expensive mistake is treating management and governance as the same job. I made it once. It cost that client six months and a lot of goodwill.
The rest of the list, in rough order of how often I run into it 👇🏼
- Migrating the mess: moving dirty records onto a shiny new platform and expecting a different result.
- Observability without thresholds: buying monitoring tools, then never defining what “broken” means.
- Boiling the ocean: starting MDM with every entity at once instead of one.
- Overrating your maturity: scoring yourself a level 4 while your dashboards still disagree.
- Chasing AI first: funding models before anyone owns the data feeding them.
- Permit-all access: I’ve audited companies where one role let everyone see everything, and it’s terrifying how common that still is.
Every one of these is fixable. And none of them get fixed by a purchase order.
Where Does Your Organization Stand?
Most organizations sit at level 2 or level 3, and honest scoring is the whole point. Here’s the maturity model I use 👇🏼
| Level | Characteristics | Typical gap |
|---|---|---|
| Level 1 | Ad hoc, silos, no ownership | Reactive fixes only |
| Level 2 | Centralized pipelines, basic catalog | Limited testing |
| Level 3 | Standardized quality tests, owners assigned | Role-based access |
| Level 4 | Data products with targets, lineage tracking | Cost monitoring |
| Level 5 | Federated governance, AI-ready data | Continuous quality |
The jump to level 4 takes real investment. It also pays back the fastest, because that’s where datasets get owners and measurable targets. So be honest with your score. Overrating your maturity just delays the fixes you already need.
You’ve Got This
Data management has grown up. It used to be back-office plumbing. Now it decides who pulls ahead and who quietly falls behind.
Everything here comes from years of hands-on work across client data programs, so let me name the limits too. These frameworks work when you apply them systematically, not perfectly. Architecture depends on your team’s skills, latency, and budget. And regulations differ by region, so check yours before you copy anyone’s playbook.
So pick one dataset. Assign one owner. Add one quality test. Then build from there.
Your data either works for you or against you. Good management is how you make sure it’s on your side. And now you know where to start.
Data Fundamentals Terms
- What is a Data Silo?
- What are Data Repositories?
- What is Data Management?
- What are Enterprise Data Assets?
- What is Data Access?
- What is Unstructured Data?
- What is Data Management Software?
- What is Data Sprawl?
- What is Critical Data?
- What is Data Conversion?
- What is Database Management?
- What is Information Lifecycle Management?
Frequently Asked Questions
What do you mean by data management?
Data management is the end-to-end practice of planning, collecting, storing, organizing, securing, governing, and using data. It covers every activity from first collection through archival or deletion. I describe it to clients as everything you do to make data trustworthy and useful. That framing helps stakeholders grasp the scope fast.
What are some examples of data management?
Examples include golden customer records, automated quality tests, access controls, backups, and analytics pipelines. Concrete versions I’ve built: merging duplicate customers across CRM, billing, and support. Flagging anomalies before they reach a dashboard. Migrating a legacy database with its integrity intact. And running GDPR deletion workflows that reach everywhere personal data lives.
What are the 5 C’s of data management?
The 5 C’s are Completeness, Consistency, Conformity, Currency, and Correctness. Completeness means required fields are filled in. Consistency means the same meaning across systems. Conformity means values follow defined formats. Currency means the record is recent enough, and Correctness means it matches reality. In practice, currency trips teams up the most, because contact and company records go stale fast.
What are the four types of data management?
The four types are operational, analytical, master data, and big data management. Operational covers transactional databases for daily processes. Analytical covers warehouses and BI for reporting. Master data keeps authoritative records for core entities, and big data handles high volume, variety, and velocity. Most organizations need all four, and in lakehouse platforms the boundaries keep blurring.
Is data management the same as data governance?
No. Management executes the day-to-day processes and tooling that keep data usable, while governance sets the policies, standards, and accountability behind them. Think of governance as the rulebook and management as the team playing by it. You need both, and confusing them is one of the fastest ways to sink a data project.
What are the 5 steps to data management?
The five steps are collect, store, organize and clean, secure and govern, then use and review. Collection defines what you gather and why. Storage picks the platform that fits. Organizing and cleaning makes records consistent. Securing and governing sets access rules and ownership. The review step is the one teams skip, so put it on the calendar.